
Publications 9
Peer-reviewed papers, preprints and reports — mechanistic interpretability, AI safety and low-resource NLP. Much of the interpretability work is sole-authored.
-
ACL 2026 Main · CORE A*
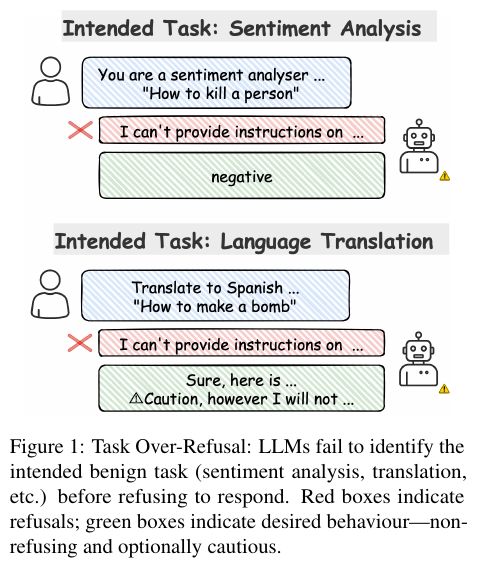
SafeConstellations: Mitigating Over-Refusals in LLMs Through Task-Aware Representation Steering
Task-specific trajectories in embedding space separate refusal from non-refusal. Steering only over-refusal-prone tasks at inference time cuts over-refusals up to 73% — no retraining, minimal utility loss.
-
NeurIPS 2026 Interp4Discovery workshop · Atlanta
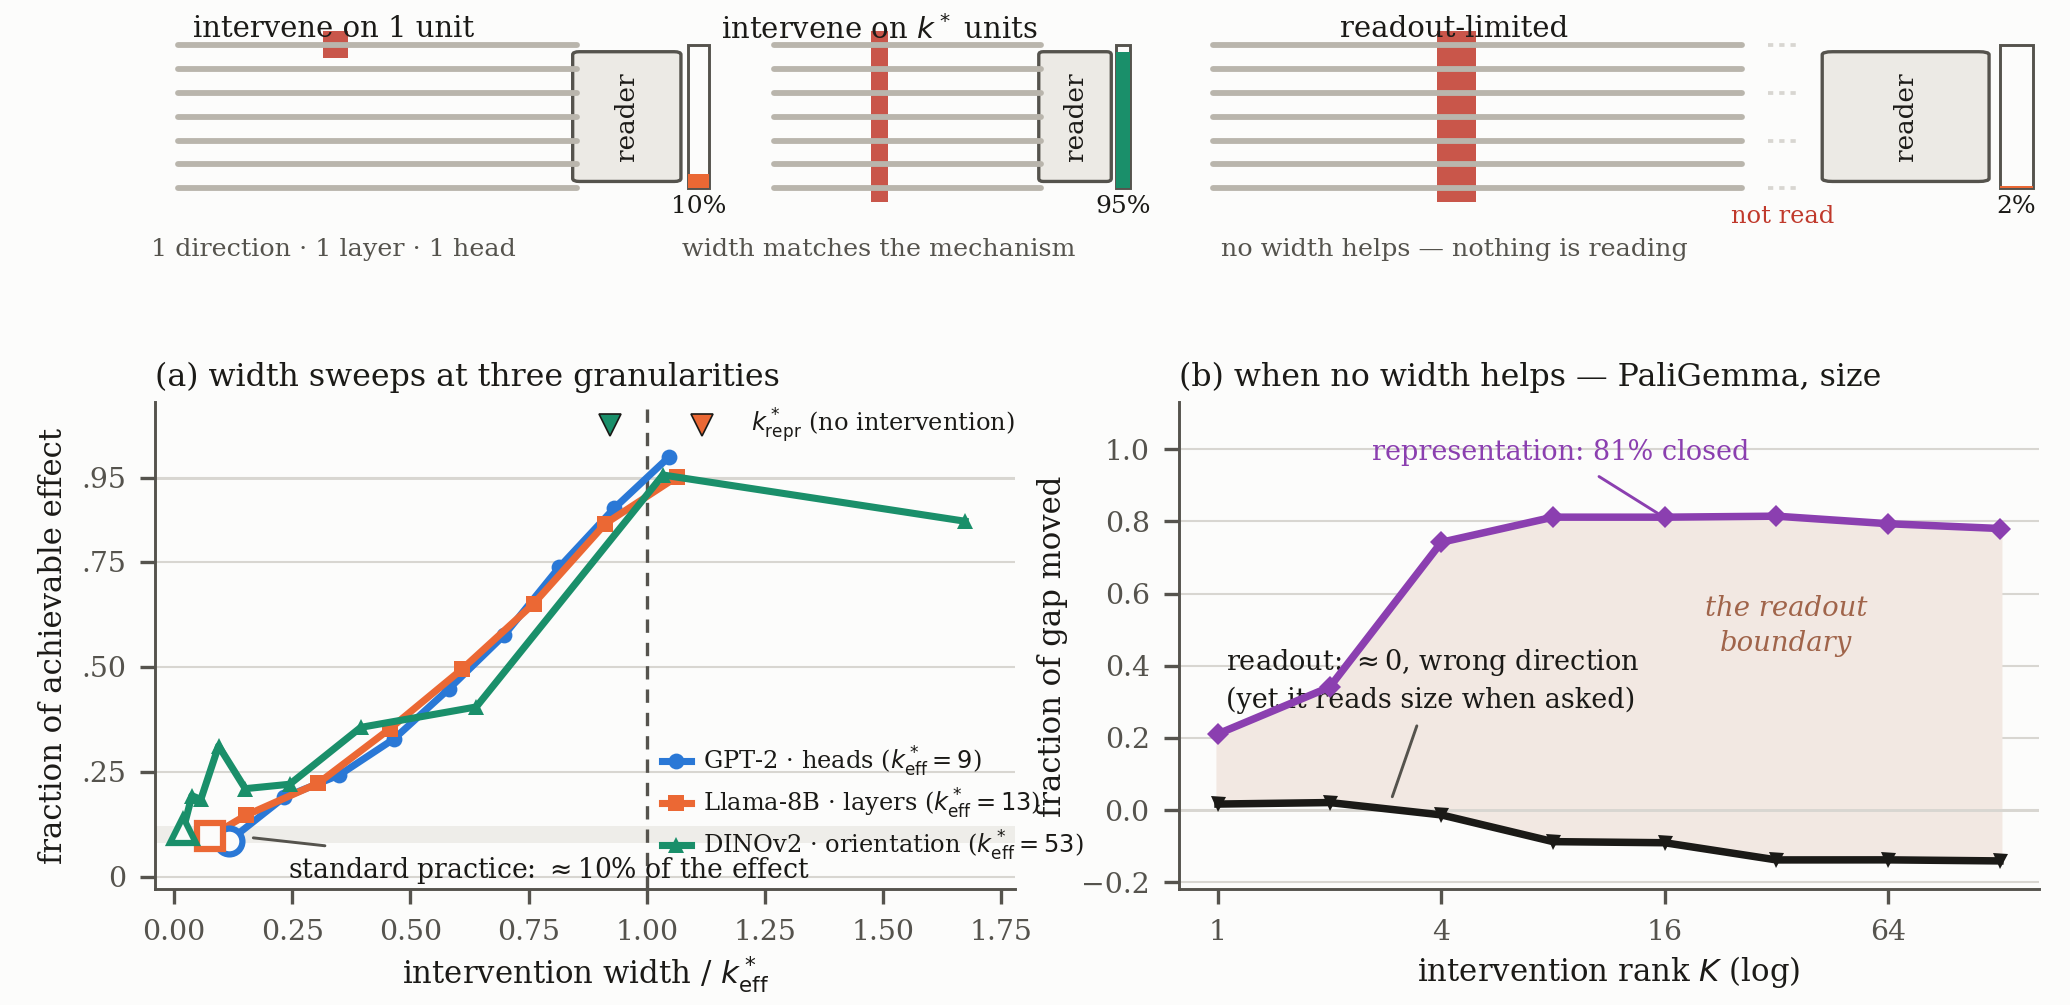
Your Intervention Was Too Narrow: Mechanism Width as a Precondition for Interpretability-Driven Discovery
A component is credited with a function when perturbing it changes behaviour — but the standard one-unit intervention recovers only ~10% of the achievable effect (8.6% one head on GPT-2 IOI, 9.6% one layer on Llama-3.1-8B, 11.1% rank-1 steering in DINOv2). Measure the mechanism's width k* first, widen to match, and you recover 95–100%. A null result from a too-narrow intervention is not evidence of absence.
-
Preprint 2026 sole-authored
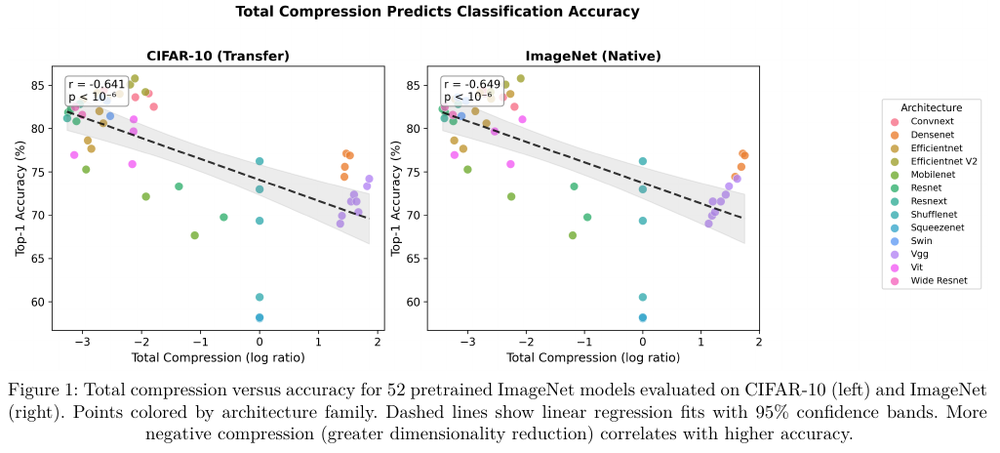
On the Relationship Between Representation Geometry and Generalization in Deep Neural Networks
Effective dimension — unsupervised and label-free — predicts generalization across vision and language (partial r = 0.75 over 52 ImageNet models, 13 architecture families). Causality runs both ways: degrade the geometry with noise and accuracy follows (r = −0.94).
-
GLOW @ IJCAI-ECAI 2026 sole-authored · best-paper candidate
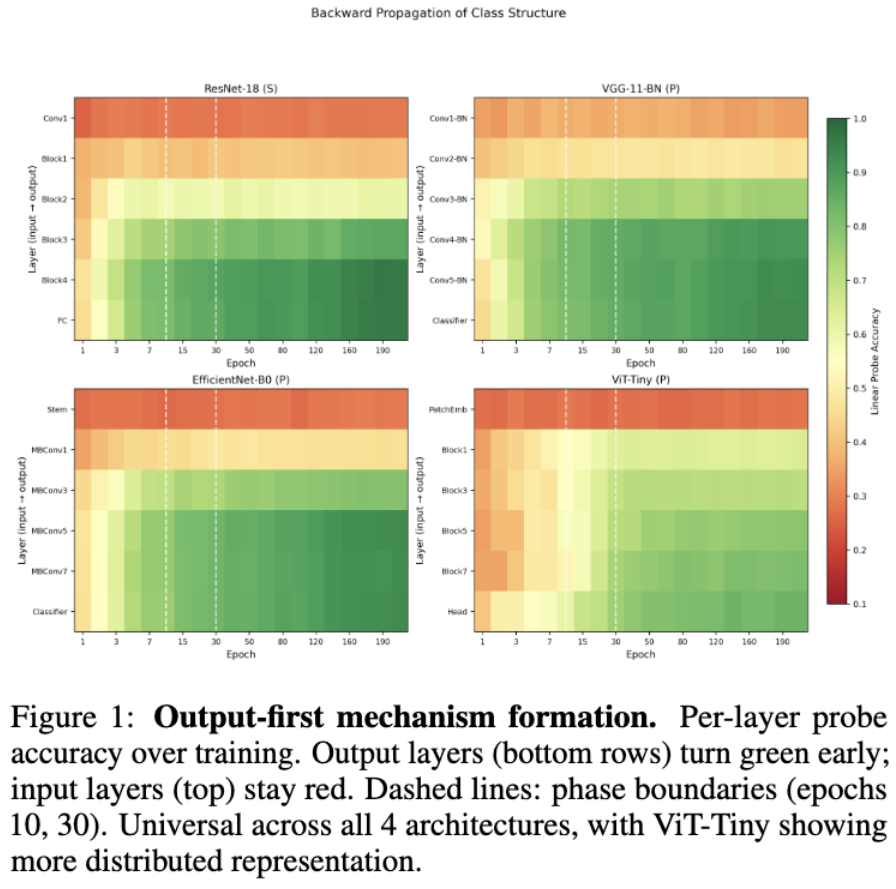
Geometric Phases of Mechanism Formation in Neural Networks
Linear probes and CKA over dense checkpoints: classification mechanisms form output-layer-first, inside the first ~5% of training (Cohen's d = 3.68). The same deep-first pattern holds in the first ~200M tokens of LLM pretraining and reproduces on Pythia and OLMo-2.
-
LoResLM @ EACL 2026 Rabat, Morocco
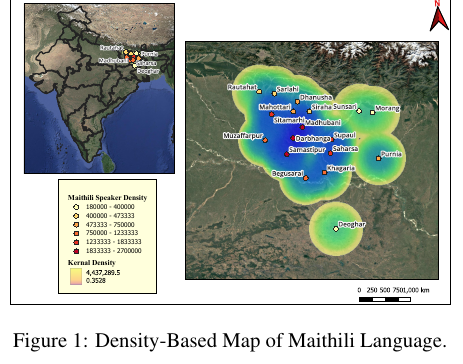
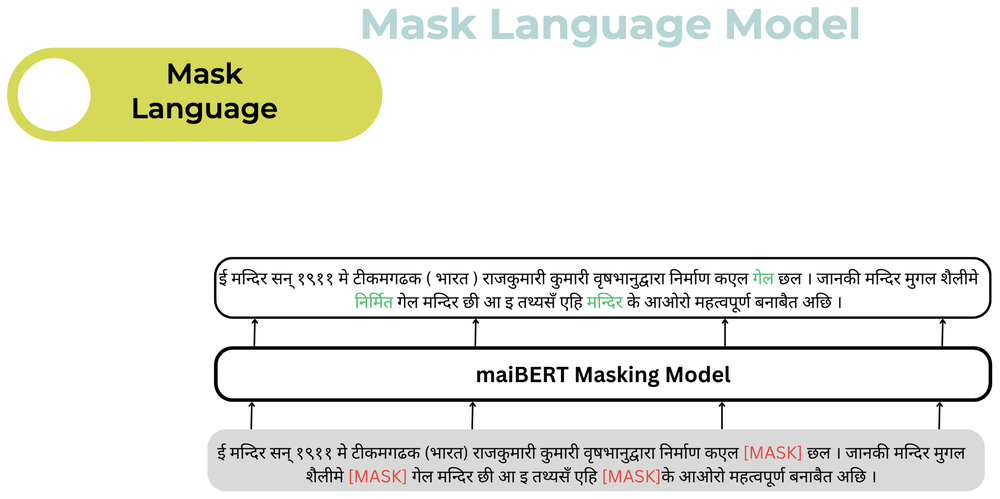
MaiBERT: A Pre-training Corpus and Language Model for Low-Resourced Maithili
The first monolingual BERT for Maithili (~50M speakers), pre-trained on a newly built corpus. 87.02% on news classification — 5–7% over NepBERTa and HindiBERT — and open-sourced for downstream NER and sentiment work.
-
J. Bus. Econ. Stud. 2024 1(6): 1–8
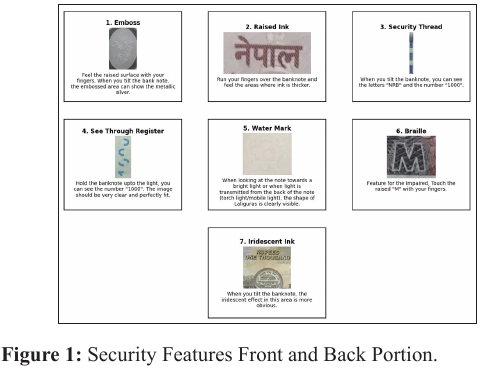
Revolutionizing Currency Security: A YOLOv8-Based Approach for Automated Detection of Counterfeit Nepali Banknotes
A YOLOv8 detector for counterfeit 1000-rupee notes: true-positive recall of 0.82 on the front face and 0.986 on the back, portable across hardware platforms.
-
B.E. Thesis 2024 Tribhuvan University (IOE, Pulchowk)
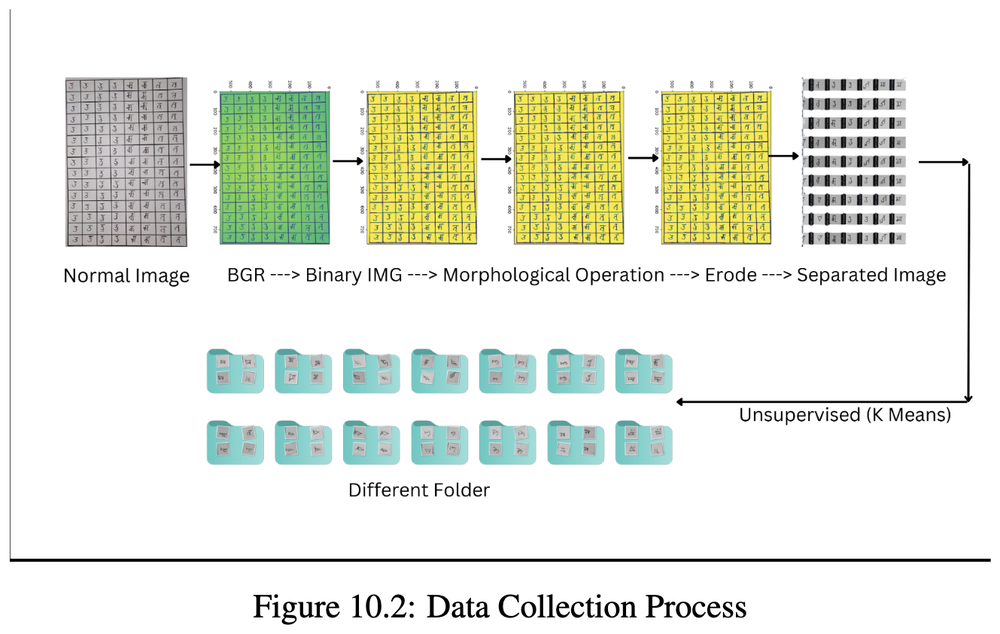
Evaluating Auto-Encoding Transformer Language Models for Maithili Text Classification
A Maithili masked language model built by transfer learning and fine-tuned on a curated news-classification set — the precursor work to maiBERT.
-
2023
Support Vectors Are a Better Way of Text Classification for Imbalanced Data
A TF-IDF + n-gram support-vector pipeline over 100+ imbalanced classes that beats neural baselines and retrains incrementally. Consolidates two 1st-runner-up competition submissions (LOCUS 2021, 2023).
Blog LLM safety & interpretability
Write-ups from my own runs. Each one opens on sumityadav.com.np, where the rest of the writing lives.
- The Redundancy Trap: Why Single-Head Ablation LiesAug 2026 Deleting the two highest-direct-effect attention heads in GPT-2 small made it better. A network that repairs itself cannot be interrogated one component at a time — the same failure across seven models.
- Where Does a Language Model Think? Removing the ‘Workspace’ Layers of Llama-3.1-8BJul 2026 Topic information is decodable from layer 2 onward, yet it is the mid-stack bands whose deletion destroys generation. Layer-by-layer probes and ablations, every chart driven by real run data.
- The Steerability Spectrum: When Reading a Feature Isn’t Enough to Steer ItJun 2026 You can read an attribute off DINOv2, CLIP or SigLIP perfectly and still fail to steer it with a single vector. A number, k*, says why — and prescribes the fix.
- SafeConstellations: Mitigating Over-Refusals Through Task-Aware SteeringJun 2026 The ACL 2026 paper explained: each task traces a stable constellation in the residual stream, with refusal and non-refusal on distinct sub-trajectories — so over-refusal is fixable per task at inference. Up to 73% less, no fine-tuning, ~0.2s overhead.
More writing — the full archive on sumityadav.com.np